This guide explains how “Pg erle CNN” can be interpreted in real-world signal-processing and analytics workflows using convolutional neural networks (CNN). Objectively, it connects the idea of layered processing (“Pg erle”) with CNN feature extraction. You’ll also find a comparison table of common pipeline options, sourcing, requirements, and a clear set of conditions for implementation.
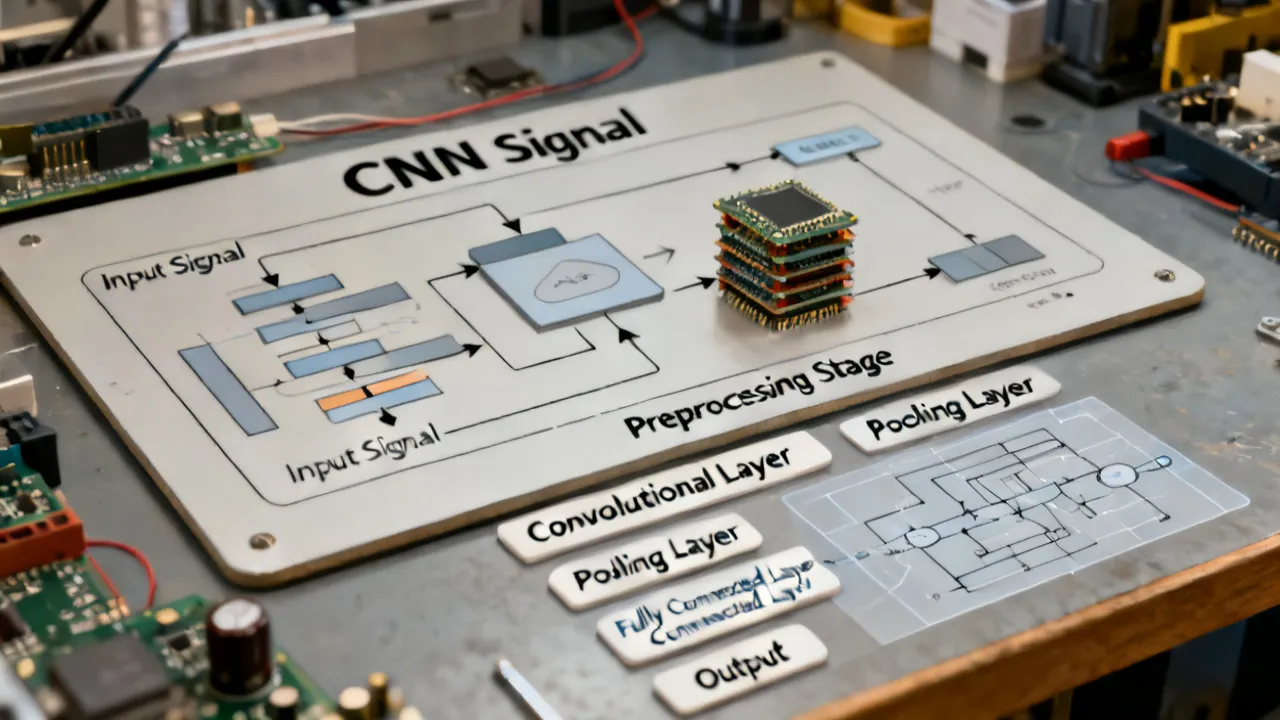
“Pg erle CNN” is best approached as a practical workflow concept rather than as a single magic algorithm. In many engineering conversations, people use “Pg erle” as a shorthand for layered preprocessing or a stage-based interpretation of raw signals, and then pair that transformed representation with a CNN for robust feature extraction and decision-making. When you view the phrase this way, the important question becomes: can your preprocessing stages produce an input representation that is stable, reproducible, and aligned with the assumptions a CNN needs in order to generalize?
In industry practice, this pairing matters because the quality of the preprocessing pipeline often determines whether a CNN learns meaningful and transferable patterns—or whether it simply memorizes artifacts introduced by an inconsistent transform. In other words: if “Pg erle” is unstable, or if it accidentally leaks information, or if it removes the very cues the CNN would need, then even a state-of-the-art CNN will fail when exposed to real operational variability.
Because “Pg erle CNN” can be discussed across multiple technical contexts (e.g., engineering logs, sensor streams, document-like feature maps, or other “page/graph/layered” representations), an objective strategy is to anchor the discussion in the role each component plays. Treat Pg erle as the stage system that shapes and conditions inputs for downstream learning, and treat the CNN as the learned extractor that converts those conditioned inputs into discriminative representations.
Below is an expanded, production-minded guide to how teams typically design, evaluate, and deploy CNN-based pipelines when the preprocessing stage is described as “Pg erle”. The emphasis is on repeatability, realistic evaluation, drift handling, and avoiding common failure modes. The narrative stays technology-agnostic and avoids unverified claims.
From a signal intelligence and ML engineering perspective, many issues attributed to “the model” are actually data-shaping issues. When people mention “Pg erle CNN,” they are frequently referencing one or more of these realities:
In other words, the “Pg erle” stage and the CNN architecture form a single system. Treating them as separate tasks—then blaming only the neural network when results drop—rarely helps. In robust engineering practice, you treat the pipeline as an integrated causal chain: preprocessing defines the information geometry; the CNN learns decision boundaries inside that geometry.
Convolutional neural networks apply learnable filters across local regions. This property works well when your input representation has meaningful locality—meaning that small shifts or local perturbations correspond to meaningful changes in the underlying phenomenon you are trying to model. In “Pg erle CNN” pipelines, teams typically convert raw or semi-structured inputs into one of the following representations.
Importantly, CNNs do not automatically “fix” poor preprocessing. When the “Pg erle” stage is unstable, the CNN can inadvertently learn the instability itself. That may yield impressive metrics on a static validation set but fail under real operational conditions where the preprocessing behavior and sensor characteristics vary.
To keep implementations dependable, focus on repeatability and evaluation discipline. In production-minded teams, “reliability” is not an abstract concept; it is achieved through constraints and checks that ensure the model sees the same semantic meaning at training and inference.
Below is a matrix-like set of pipeline options that often appear in industry, with a clear interpretation of where “Pg erle” fits, what the CNN does, and what risks you should watch.
| Pipeline Option (Comparison) | Where “Pg erle” Fits | Typical CNN Role | When It’s a Good Fit | Common Risk to Watch |
|---|---|---|---|---|
| Stage-based normalization + fixed transforms | Deterministic preprocessing (scaling, binning, alignment) | Learn discriminative patterns from stable tensors | When input characteristics are consistent enough | Distribution shifts between training and deployment; normalization mismatch |
| Learned front-end + CNN backbone | Often partially learned or adaptive steps | End-to-end feature learning | When preprocessing variability is high | Hard-to-debug failure modes; learned steps may encode shortcuts |
| Hybrid rules-to-features + CNN classifier | Rules generate candidate feature maps | Refine classification from candidate maps | When interpretability is important or labels are scarce | Rule bias restricting the signal space; subtle errors in rule logic |
| Self-supervised pretraining for CNN | Creates augmented “views” of the same underlying signal | Build robust representations before labels | When labeled data is limited | Augmentations that destroy relevant invariances; overlap leakage |
Two meta-requirements cut across all these options:
Use this as a structured starting point. The aim is not to force one architecture or one preprocessing style, but to ensure the system is evaluated under realistic conditions. Each step corresponds to a category of failure that occurs in real projects.
In many organizations, “Pg erle CNN” discussions end up in one of two evaluation frameworks: model-centric or system-centric. The system-centric approach tends to be more informative when preprocessing is explicit and structured.
Because “Pg erle” strongly implies a staged input process, system-centric evaluation is usually more valuable. It enforces accountability for both the input transformations and the learned model behavior. Additionally, it helps you identify where the failure happens:
Your prompt mentions “price information” and “supplier details,” but no specific verifiable values were provided. In real procurement and implementation planning, teams rarely treat cost as one number. Instead, they break cost into buckets that map to actual deliverables: compute, data preparation labor, engineering time, and ongoing operations.
Rather than guessing figures, a professional approach is to request quotations tied to scope, such as data volume, augmentation and preprocessing complexity, training duration, and integration requirements. If you have a shortlist of suppliers, you can evaluate them objectively using criteria such as:
If you share your deployment environment (on-prem, cloud, or edge), the expected inference rate, and the nature of your signals, I can help you convert that into a practical request-for-quote checklist. The key is to ensure the supplier’s process matches your system-centric evaluation expectations.
Your instructions include a rule about location placeholders. Since no explicit city or country appears in the provided keywords, this section uses a general “nearby” framing. In practice, “nearby” sites (different facilities, regional installations, or adjacent operational contexts) often show small but meaningful operational variation. These differences might include equipment calibration offsets, local noise profiles, differences in maintenance routines, or differences in environmental factors.
For “Pg erle CNN” reliability, these variations matter because preprocessing stages may inadvertently encode assumptions about the environment. For example:
Design “Pg erle” stages to be consistent while validating cross-site performance. A robust approach is to include “nearby context” data during evaluation and to treat it as a separate test regime rather than randomly mixing it with training data. When cross-site generalization is a requirement, you should also test whether drift monitoring at the “Pg erle” stage can detect differences early enough to trigger re-calibration or retraining.
“Pg erle” is not a universally standardized term in public literature. In practice, it usually denotes a staged preprocessing or transformation sequence applied before a CNN. The safest and most reliable meaning is the one you define in your own pipeline documentation: what happens at each stage, in what order, with what parameters, and with what constraints. The key is to document each transformation so the pipeline is reproducible.
When teams say “Pg erle,” they may also imply a pipeline that resembles pages/layers/graphs. If that is your case, define whether “Pg erle” produces:
No. If “Pg erle” produces feature maps that are highly separable—meaning the classes differ in structured ways that a simple model can exploit—then alternative models can be sufficient. Examples include logistic regression, linear SVMs, gradient-boosted trees on engineered features, or lightweight CNNs.
However, CNNs are often chosen when:
Use ablation studies and sanity checks. Ablation means training and evaluating with and without each “Pg erle” stage. Sanity checks include visualizing input tensors and ensuring they have stable statistical properties across training and inference.
Concrete tests that often reveal preprocessing harm:
Choose metrics matching the task type and operational goals.
In signal intelligence, you often care about “operationally meaningful errors,” not only average metrics. For example, in event detection, the cost of missing a rare event can be far higher than the cost of extra alerts. Therefore, calibrate thresholds to optimize a cost-sensitive objective or an operational utility metric.
Handle drift at two levels: monitoring drift in the “Pg erle” output and monitoring drift in CNN predictions. If you detect drift, decide whether you can:
Practical drift handling steps include:
For trustworthy, widely used evaluation practices and references on CNNs and deep learning workflows, consult reputable sources such as peer-reviewed literature, and official deep learning framework documentation. Recommended topics include training stability, regularization, proper split methodology, and evaluation under distribution shift.
As you expand your pipeline, pay special attention to:
Often, yes—especially if “Pg erle” involves transforming sensitive signals or personal data. Even if the model does not directly expose sensitive content, the training pipeline can handle sensitive inputs. Ensure your data handling follows applicable privacy and security requirements, including:
In many organizations, compliance review also expects documentation of pipeline stages (“Pg erle” steps included) and a clear explanation of how data is used, retained, and secured.
For general CNN background and evaluation methodology, reputable sources include foundational deep learning texts and well-known peer-reviewed papers. Examples include:
Additionally, for “Pg erle” style preprocessing, you should consult references relevant to your signal modality (e.g., time-frequency transform methodology for audio/RF/vibration, or geospatial normalization methodology for spatial sensor layouts). The best preprocessing references are typically modality-specific because they connect transform parameters to physical meaning.
It is useful to spell out common ways these systems fail so you can design checks that prevent them early. Below are patterns that frequently appear in projects, along with practical mitigations.
This often stems from hidden leakage or overly optimistic splits. For example, “Pg erle” might compute normalization statistics using data that implicitly includes future windows. Or the evaluation split might allow the model to see device-specific artifacts it will not see in real deployment.
Mitigation: enforce strict separation by device/site/time. Implement “Pg erle” exactly as it will run at inference time and ensure that any statistics derived from data are computed only on training data for the relevant scope.
The CNN may latch onto quirks introduced by “Pg erle”: repetitive padding artifacts from windowing, histogram binning boundaries, quantization patterns, or deterministic filtering artifacts. The model then performs well when those quirks are present, but fails when conditions shift.
Mitigation: perform ablation to verify stage necessity, and augment training data in ways that preserve the real-world invariances while changing irrelevant artifacts. Also visualize intermediate tensors to see if class separation appears even without the CNN.
Because “Pg erle” is a stage pipeline, a small parameter change (e.g., normalization epsilon, window overlap, or histogram bin edges) can shift input distributions. If the CNN is sensitive to those shifts, performance may drop unexpectedly.
Mitigation: version preprocessing code and parameters. Use automated regression tests: compare output tensors statistics across builds to catch unintended changes.
In detection tasks, the positive class can be rare. Accuracy can look high even when the model misses most events. If you optimize for the wrong metric, you can inadvertently train a model that favors the dominant negative class.
Mitigation: use cost-sensitive losses, sample balancing strategies, and metrics that reflect operational priorities (per-class recall, PR-AUC, event-level metrics).
Signal intelligence is very sensitive to time alignment. If labels correspond to events that occur between windows, or if there is an offset between sensor readings and labeling timestamps, the CNN learns inconsistent mappings.
Mitigation: validate alignment by plotting representative samples and verifying the event boundaries. Consider adding alignment tolerance during training or using target smoothing strategies if appropriate.
Even if the pipeline is accurate, “Pg erle” may be too slow. The CNN may run fast on a GPU/accelerator, but the preprocessing stage might be the bottleneck. In real deployments, you often need strict latency.
Mitigation: benchmark end-to-end latency including “Pg erle,” optimize transform implementation, consider lower-resolution inputs, and test edge deployment constraints early.
Since the meaning of “Pg erle” depends on your domain, the key is to ensure your stages are coherent in how they handle scale, alignment, and information retention. Below are general considerations applicable to many signal modalities.
Normalization is often a central “Pg erle” decision. Per-window normalization can remove amplitude information that may be discriminative. Global normalization can be sensitive to data distribution shifts if done incorrectly (e.g., computing statistics using the full dataset). Per-device normalization may help if device characteristics are stable, but can fail if devices change over time.
Practical approach: compare normalization strategies using an ablation study and evaluate on a split that mimics deployment. If amplitude encodes meaningful classes, prefer normalization approaches that preserve those cues.
In time-frequency representations, how you window the signal strongly affects the learned patterns. Overlap affects temporal resolution and redundancy. Window function choice (e.g., Hann vs rectangular) affects spectral leakage.
Practical approach: decide the windowing strategy based on event duration and the operational requirement for timing accuracy. Evaluate detection performance at the event level rather than just frame-level accuracy.
“Pg erle” often includes steps like binning or quantizing. Quantization can introduce discretization boundaries that the CNN may exploit spuriously.
Practical approach: if quantization is necessary for latency, ensure you evaluate whether the CNN learns genuine signal patterns rather than bin-edge artifacts. You can test this by varying quantization resolution slightly during training and checking performance stability.
Operational sensors may drop samples. If “Pg erle” fills missing values in a deterministic but biased way, the CNN may learn dropout patterns as class cues.
Practical approach: incorporate missingness indicators as additional channels or design imputation methods that reflect uncertainty. Evaluate on dropout-simulated data that matches real dropout statistics.
Once “Pg erle” outputs tensors, the CNN architecture must be compatible with the representation. Several practical considerations help.
If the tensor is a time-frequency map, locality corresponds to local spectral-temporal patterns. If the tensor is a spatial grid, locality corresponds to neighboring spatial regions. If the tensor is a reshaped graph embedding, locality may be artificial, making standard CNN inductive bias questionable.
Practical approach: verify whether convolutional features correspond to meaningful neighborhoods by inspecting learned feature activations or performing controlled perturbation tests.
Augmentation should change irrelevant aspects while preserving class-defining structure. For signal intelligence, common augmentation ideas might include adding noise consistent with operational background, slight time shifts within alignment tolerance, or mild amplitude scaling if physically plausible.
Practical approach: test augmentations for invariance correctness. Over-aggressive augmentation can remove discriminative cues and cause the CNN to underfit.
Even small numerical issues can destabilize training. For example, extremely large values from “Pg erle” outputs can cause gradient issues. Extremely small values can cause underflow and poor learning.
Practical approach: normalize inputs to a reasonable scale, inspect tensor ranges, and use training stabilizers as needed (learning rate schedules, gradient clipping, batch norm or layer norm choices consistent with your batch size regime).
Reliable signal intelligence systems require more than a good training run. They require monitoring and guardrails that handle uncertainty and drift.
At minimum, store and monitor:
When drift occurs, you want to know whether it is caused by sensors, by “Pg erle” code changes, by environment changes, or by upstream data formatting issues.
Track:
If prediction distribution shifts sharply, it may indicate drift, sensor faults, or a pipeline change. Guardrails can include:
In many intelligence workflows, you choose action thresholds. If the CNN’s predicted probabilities are not calibrated, thresholds can be mis-set leading to too many false alerts or missed detections.
Practical approach: calibrate on a representative validation set and periodically recalibrate if drift is detected. Use reliability diagrams or calibration metrics as part of your evaluation.
When labels are expensive, teams often deploy with human verification for uncertain cases. If you do this, ensure that the labeling pipeline remains consistent with “Pg erle” preprocessing definitions and that new labels do not introduce policy drift.
To make “Pg erle CNN” tangible without assuming a specific domain, consider a generic workflow for an event classification task on time-series data.
Imagine your pipeline receives a continuous sensor stream. You define “Pg erle” as a stage pipeline that: (1) segments the stream into fixed-length windows, (2) aligns each window to timestamps, (3) applies a transform to produce a time-frequency map, (4) normalizes the map using training-derived statistics, (5) optionally removes noise using a deterministic filter rule, and (6) outputs a fixed-size tensor to the CNN.
Then, the CNN is trained to classify each window or detect whether an event is present. A system-centric evaluation would test on: windows from the same devices (easy), windows from new devices (harder), windows from later time periods (realistic drift), and windows under simulated background interference.
If you see a gap only when evaluating on later time periods, it strongly suggests that “Pg erle” normalization or filtering is too tied to older conditions. If you see a gap when evaluating on new devices, you may need per-device normalization or improved calibration. If you see a gap only when detection is close to boundaries, you may need alignment adjustments and more precise labeling windows.
This example illustrates how the “Pg erle” stage definition and evaluation split strategy often explain outcomes far more than CNN depth does.
Below is a practical checklist you can apply before considering the system production-ready. This is especially useful for “Pg erle CNN” projects where preprocessing is complex and easy to misinterpret.
Interpreting “Pg erle CNN” as a pipeline system—where “Pg erle” defines how input signals are shaped and the CNN learns hierarchical features—offers a far more reliable route than treating preprocessing and modeling as independent tasks. Start by precisely documenting the “Pg erle” stages, choose a CNN-compatible representation, and evaluate under realistic splits and operational variations, especially if deployment spans “nearby” sites where calibration and background conditions differ.
If you share the exact meaning of “Pg erle” in your setting (for example: your preprocessing steps, your input format, and your task type), you can get a tailored plan for metrics selection, ablation priorities, drift monitoring design, and practical guardrails for deployment. The most valuable next step is not choosing a bigger CNN; it is making your “Pg erle” stages measurable, stable, and aligned with how the model will operate in the real world.



Este artículo explica cómo usar un Simulador Bb para estimar importes y tomar decisiones con criterio. Se describen, de forma objetiva, qué suele medir un simulador de presupuestos, qué variables influyen en los resultados y por qué conviene contrastar la cifra con la información oficial del proveedor. Además, se ofrecen criterios de evaluación, condiciones típicas y respuestas a preguntas frecuentes.
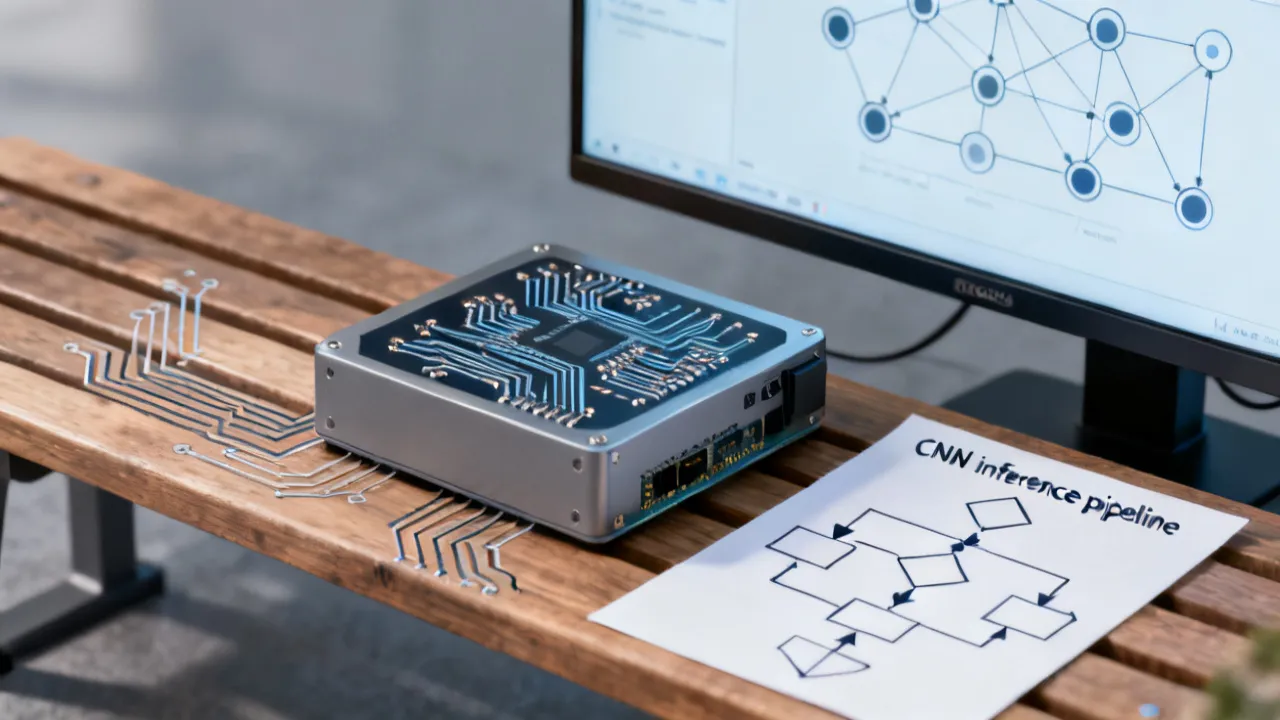
This guide explains how “pg erle CNN” architectures work in real deployments, from dataset choices and training workflow to inference optimization and verification. The background covers what CNNs do, why data quality matters, and how pipeline constraints influence model accuracy, latency, and maintainability—using careful, objective framing aligned with industry practice.
This guide explains how “Pg erle CNN” can be interpreted in real-world signal-processing and analytics workflows using convolutional neural networks (CNN). Objectively, it connects the idea of layered processing (“Pg erle”) with CNN feature extraction. You’ll also find a comparison table of common pipeline options, sourcing, requirements, and a clear set of conditions for implementation.
This guide explains the adult-content market’s structure, compliance expectations, and risk factors, focusing on how terms like Xnxx are discussed online. Objectively, keywords used for search often reflect browsing behavior, platform moderation, and regional enforcement patterns. The article also reviews buyer-side due diligence, supplier screening concepts, and practical safeguards for safer, policy-aligned engagement.
This guide explains how to evaluate supplier performance and lead times using the reference 13327049726. It provides objective background on how identifiers like this are commonly used in procurement workflows, what buyers should verify (capacity, QC, logistics readiness), and how pricing and supplier practices affect delivery reliability for industrial procurement decisions.
This guide explains how to evaluate supplier and pricing information tied to 13327049726, and how to verify that a quote aligns with operational requirements. Objectively, the keywords signal a contact-driven sourcing workflow—where numbers, documentation, and supplier capability matter. The article outlines what to check, how to compare offers, and what conditions reduce risk.

